Document Deduplication
If you're using Datastreamer Searchable Storage, documents are automatically deduplicated based on their id field. Searchable Storage also upserts: when a document arrives with an id that is already stored, the newer version updates the stored document rather than adding a second copy.
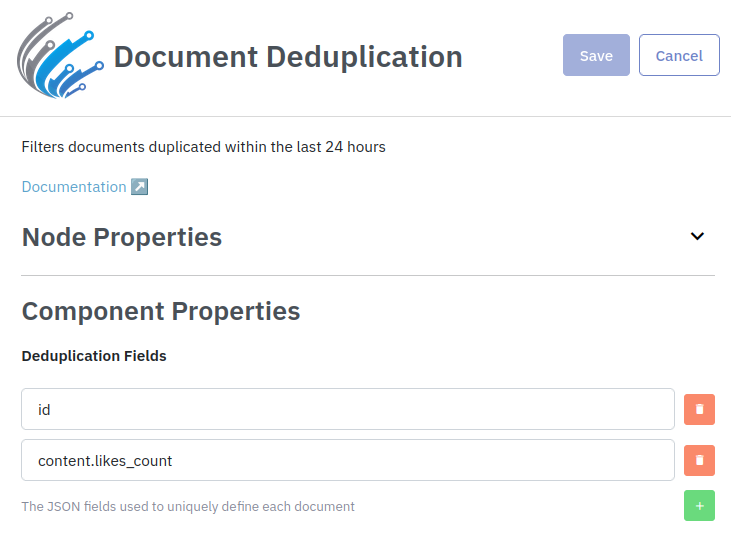
For clients not using Datastreamer Searchable Storage, similar deduplication can be achieved by including the Document Deduplication connector from the catalog. This component filters out duplicates within a 24-hour window.
By default, the connector uses the id field in each JSON document to identify duplicates. However, this may unintentionally filter out important updates (e.g., changes in social media engagement). To avoid this, you can specify additional fields when configuring the connector, allowing meaningful updates to pass through.
Connector outputs
The connector has two outputs, so you decide what happens to each set of documents:
- Left: the deduplicated content. Connect this to the next step in your pipeline.
- Right: the duplicate content. Send it wherever you need it, such as a storage destination to keep a copy, or the Trash Can component to discard it.
Updated 14 days ago